IMRaD Analyzer AI SaaS for research papers
An AI that reads research papers, with free and Premium accounts.
The need
Help researchers see how an introduction is built, sentence by sentence, without rereading it all.
What we built
An online service with PDF upload, AI analysis, history, an admin dashboard, and free and Premium plans.
- Next.js
- FastAPI
- BERT
- Gemini
The results
- 98,21 %
- accuracy (F1)
- 169 000
- labelled sentences
- 3
- access tiers
What the app does, screen by screen
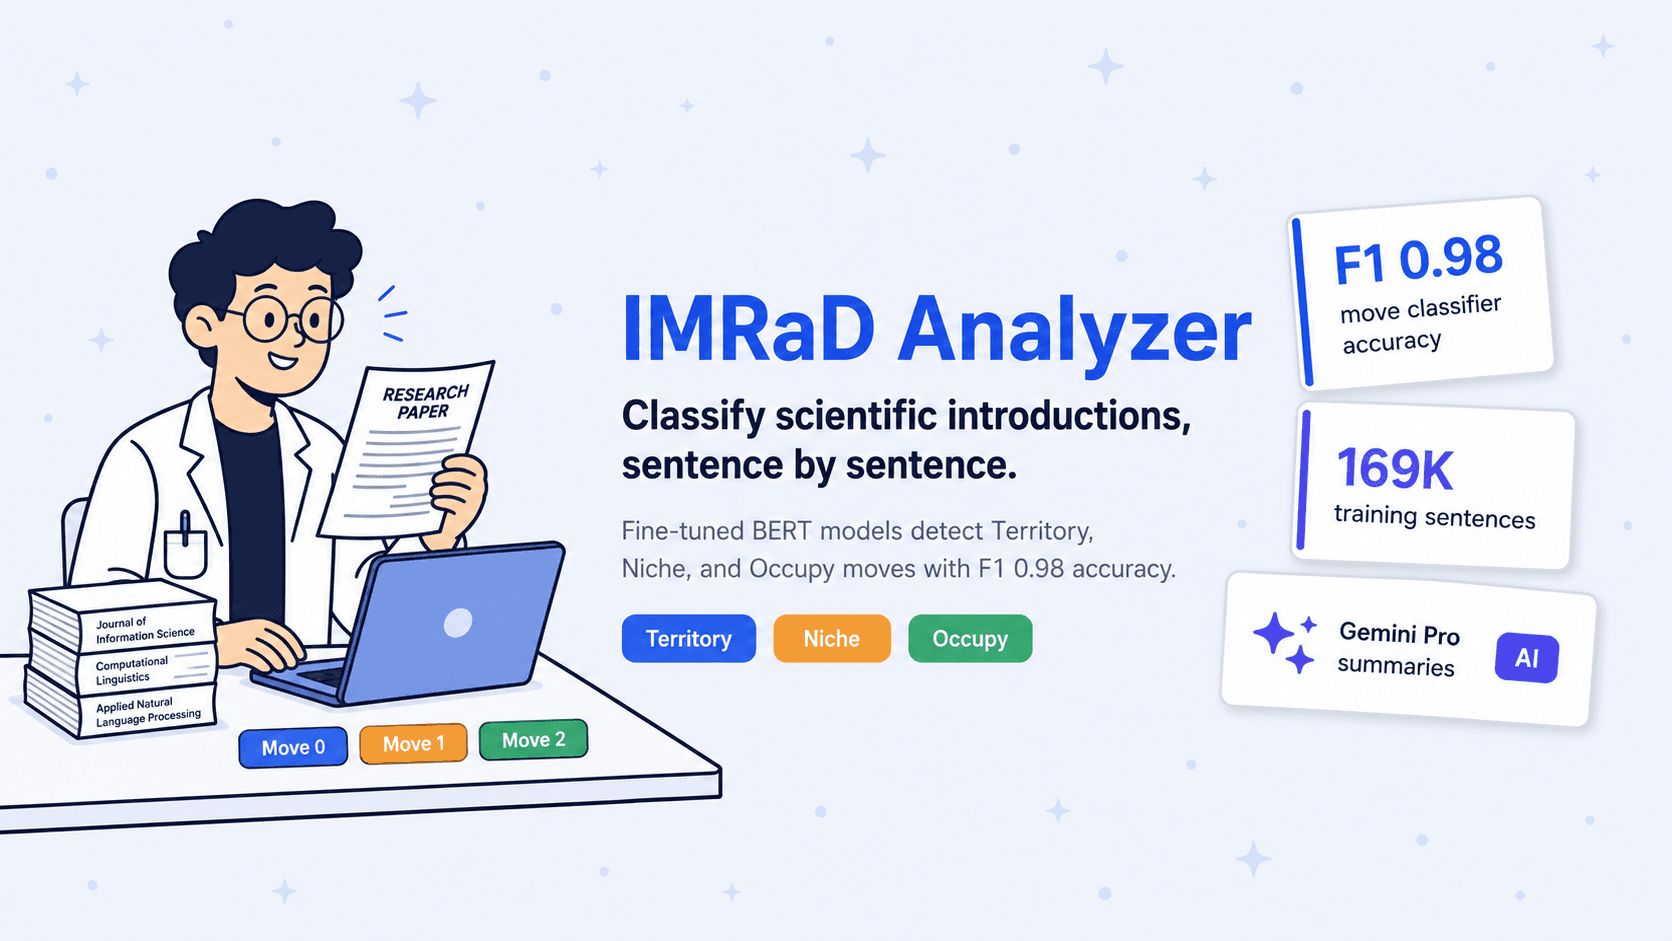
IMRaD Analyzer promotional thumbnail
- Fine-tuned BERT cascade classifies every sentence in a scientific introduction into Territory, Niche, or Occupy moves.
- Custom 169K-sentence training dataset built with a 3-step Gemini Pro pipeline achieves a peak F1-score of 98.21%.
- Distributed 8-node microservice architecture handles PDF extraction, classification, AI analysis, and user management.
8-node Microservice Architecture.
- Nginx (gateway)
- Spring Cloud Eureka (discovery)
- Next.js (frontend and API)
- PDF extractor (FastAPI)
- Tensorflow Serving
- Moves and Sub-moves AI microservices (FastAPI with langchain)
- User data microservice (MongoDB, Express.js)
- Redis as a message broker.
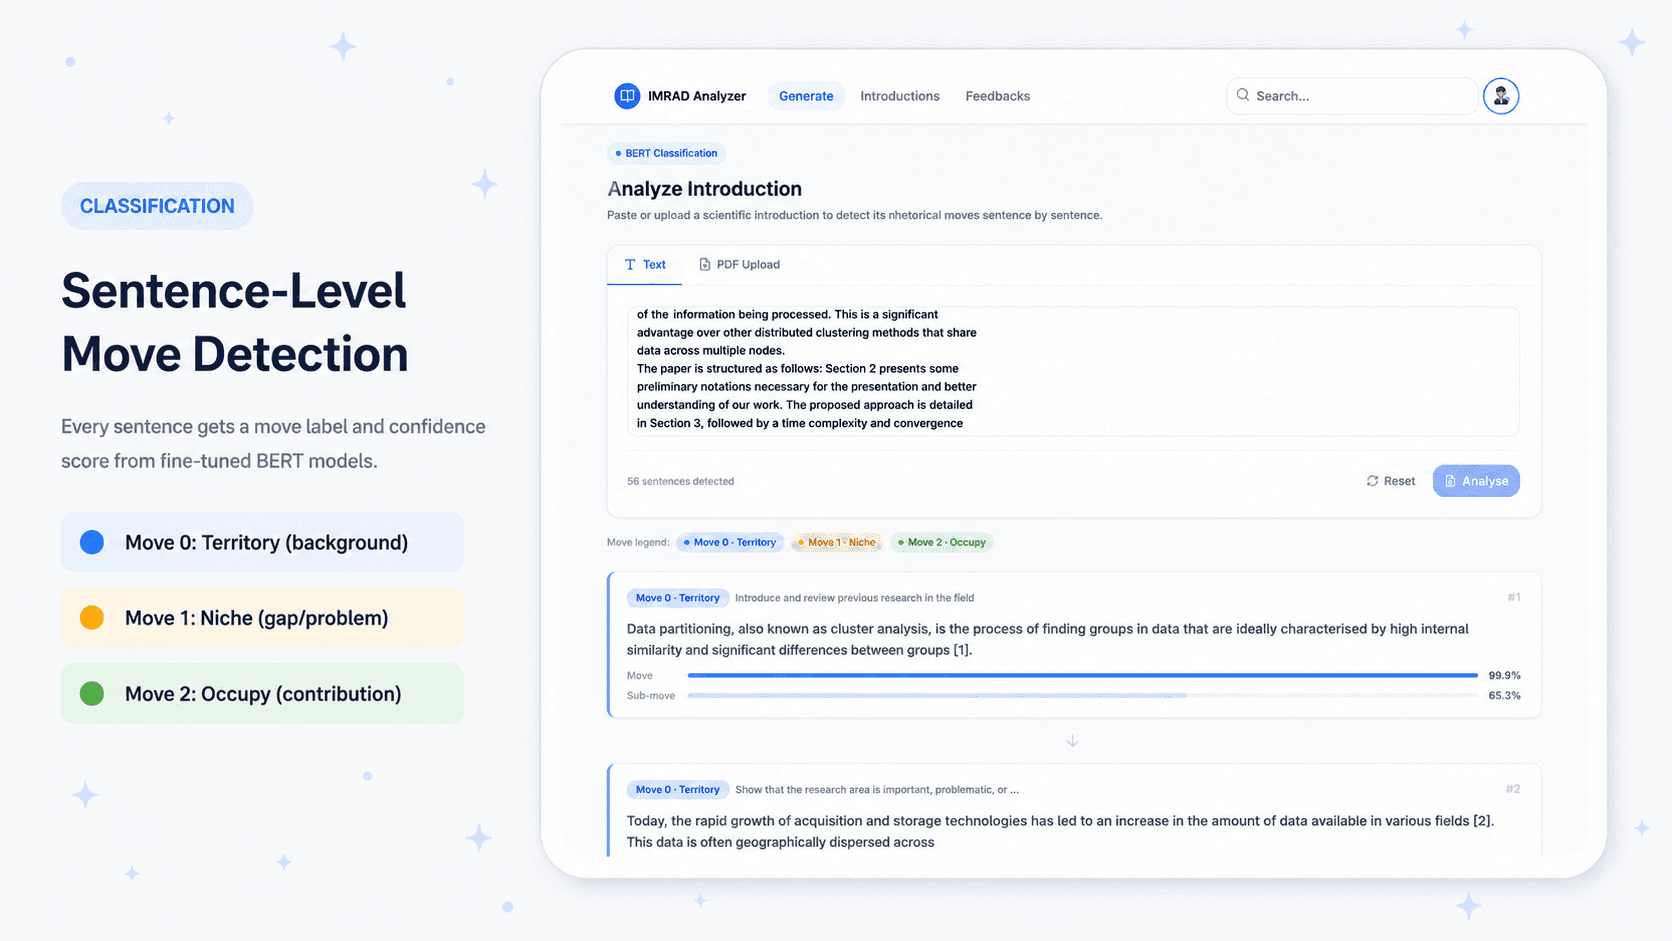
Sentence-Level Move Detection
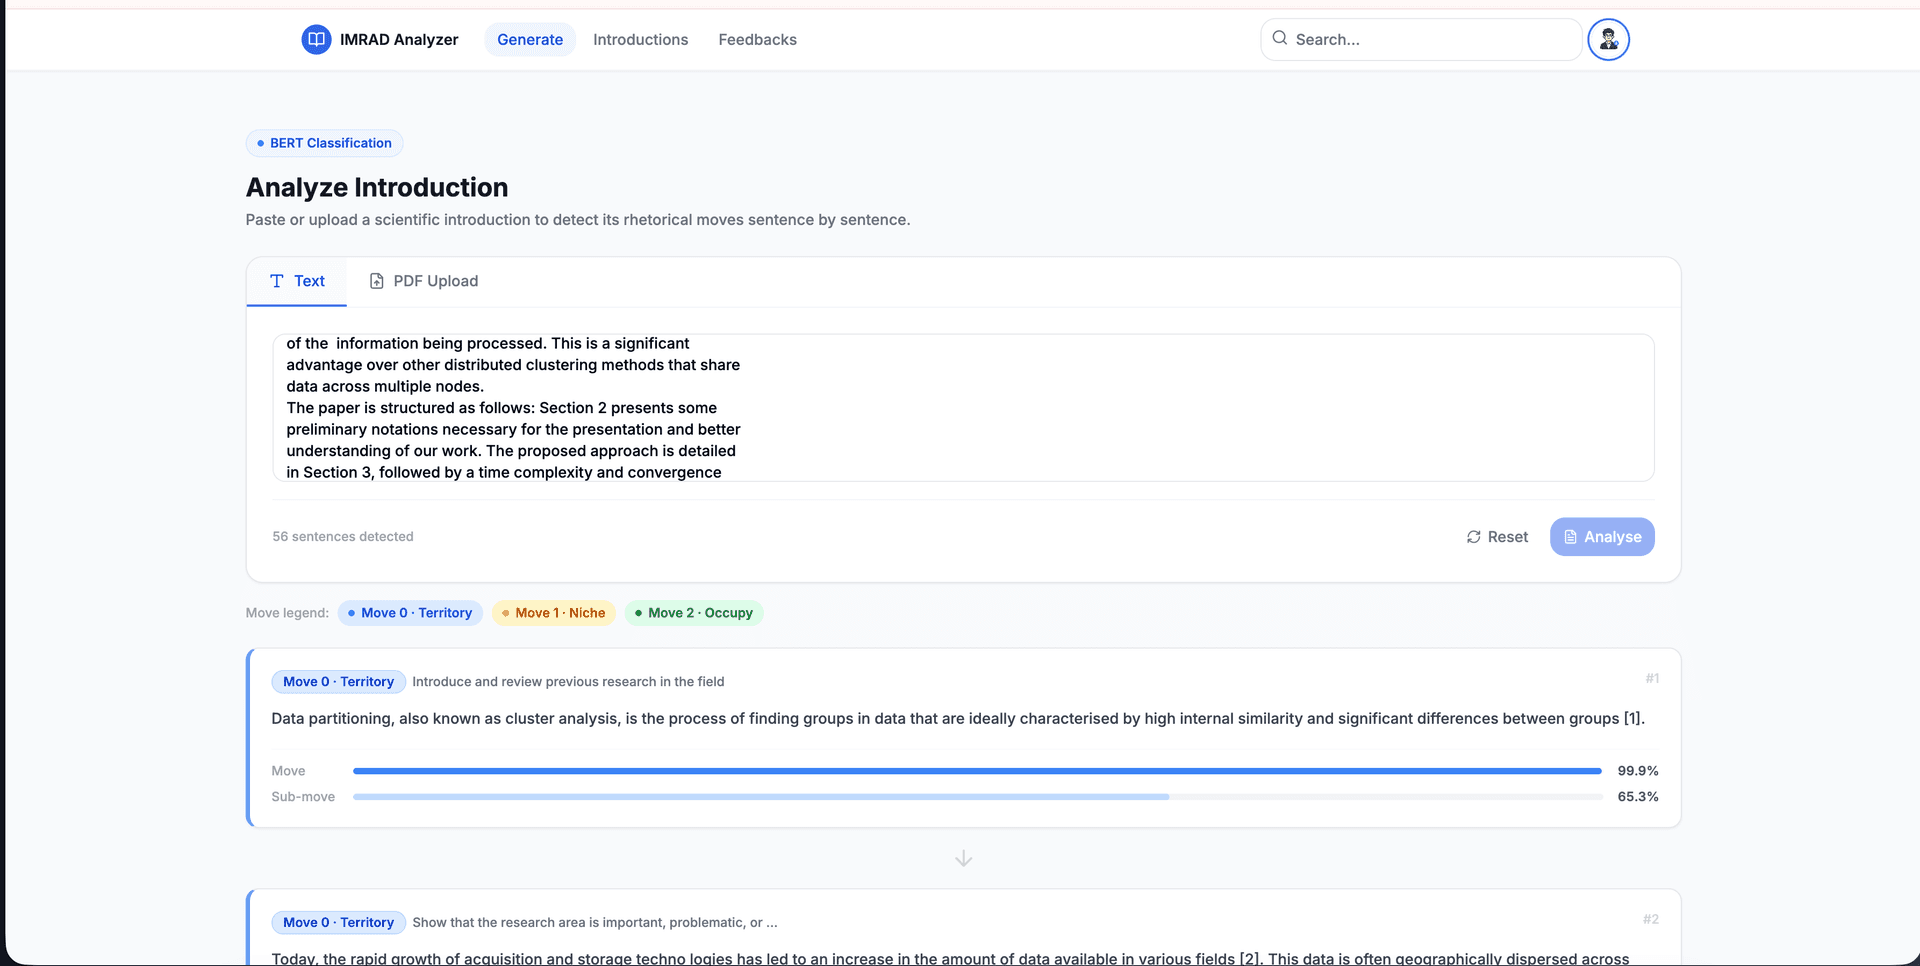
- Every sentence in a scientific introduction is labeled with its IMRaD move (Territory / Niche / Occupy) and sub-move in real time.
- Color-coded badges (blue, amber, green) and per-sentence confidence bars make classification results immediately readable.
- A cascade of four hierarchical fine-tuned BERT models drives the full pipeline, served via TensorFlow Serving.
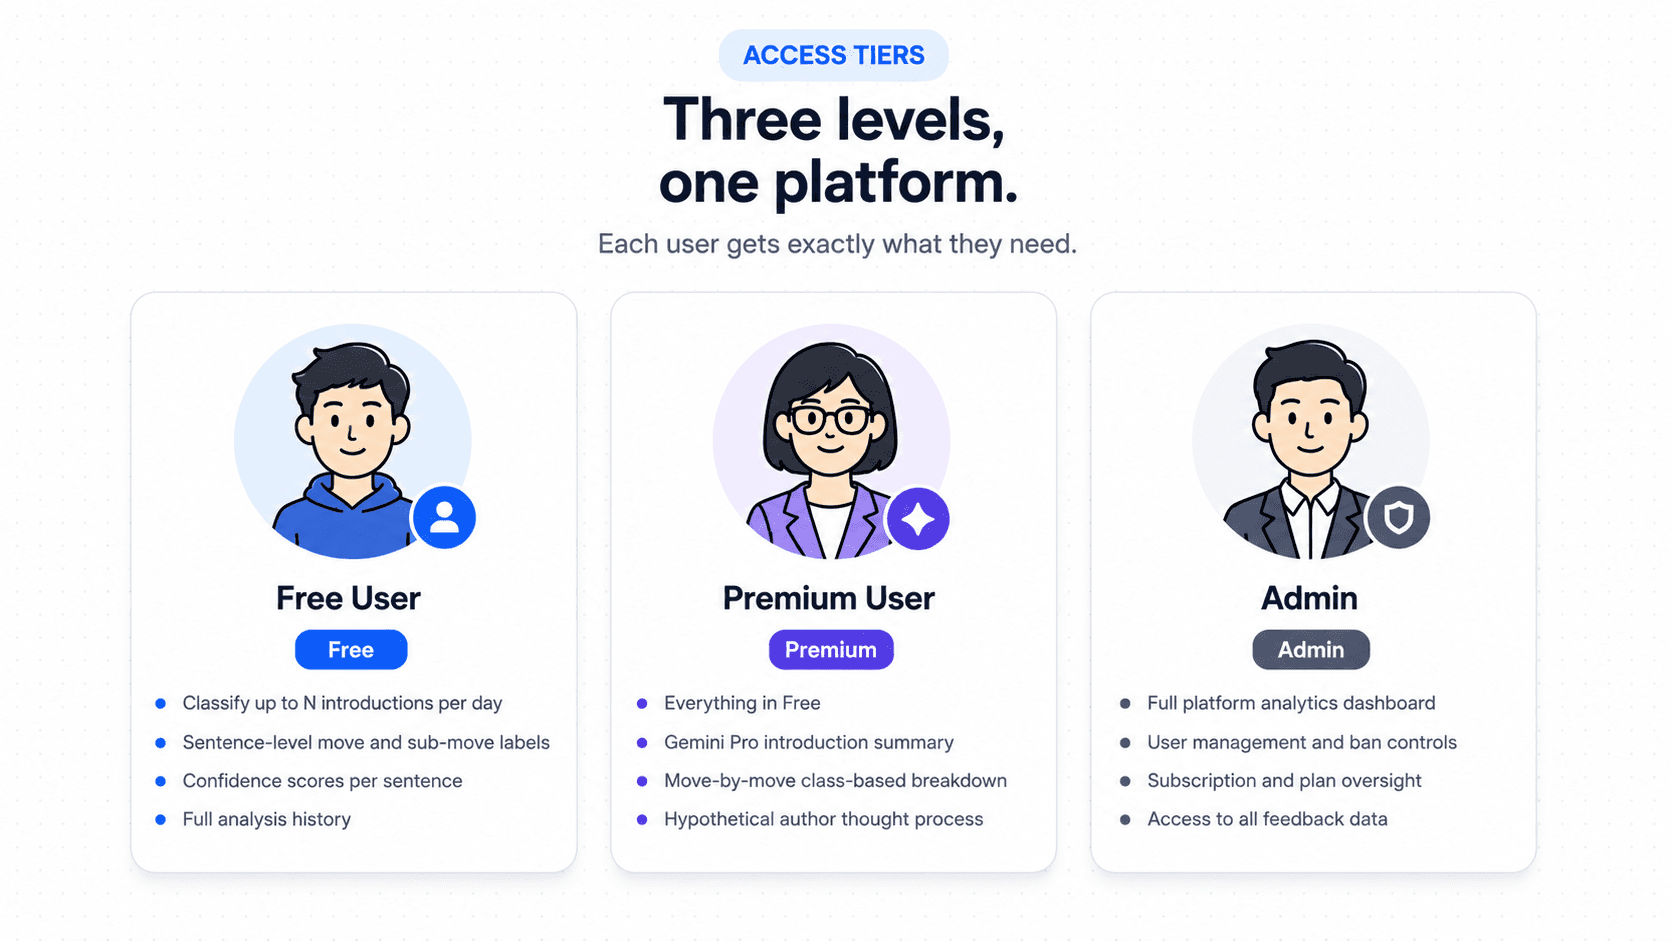
Three-Tier Access Model
- Free users classify introductions, view sentence-level labels and confidence scores, and access their full analysis history.
- Premium users unlock Gemini Pro summary, class-based move breakdown, and hypothetical author thought process.
- Admins get platform-wide analytics, user management, subscription oversight, and full access to all feedback data.
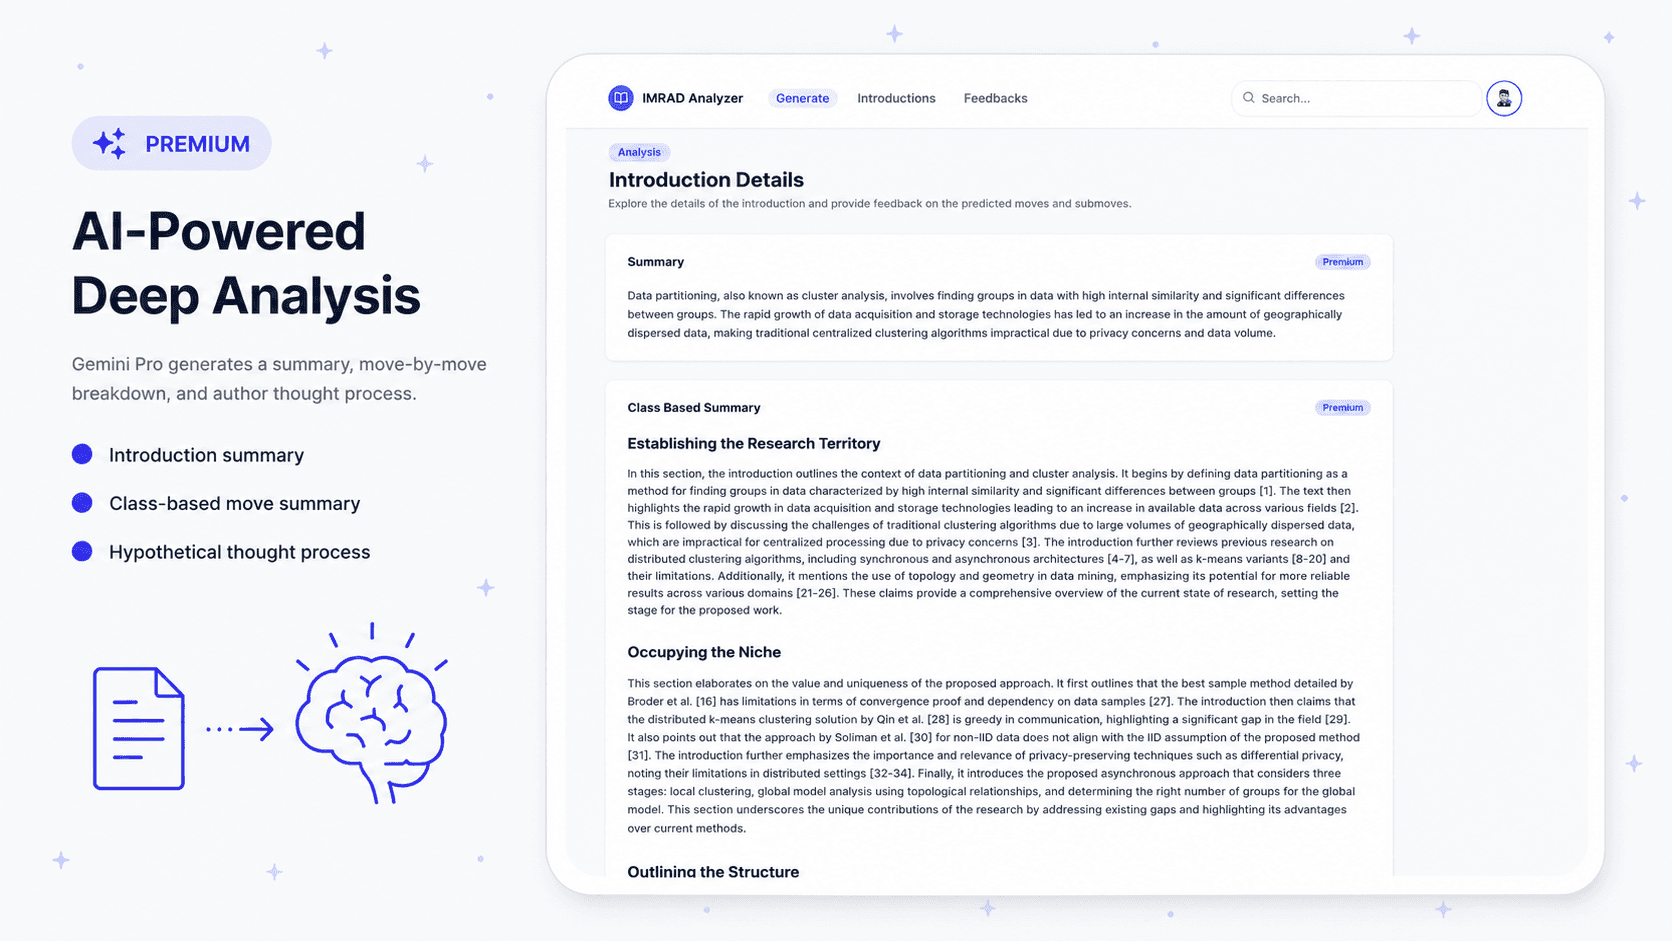
AI-Powered Deep Analysis
- Premium users receive a Gemini Pro-generated introduction summary, move-by-move class-based breakdown, and hypothetical author thought process.
- All three sections stream asynchronously via Redis pub/sub so results appear progressively without blocking.
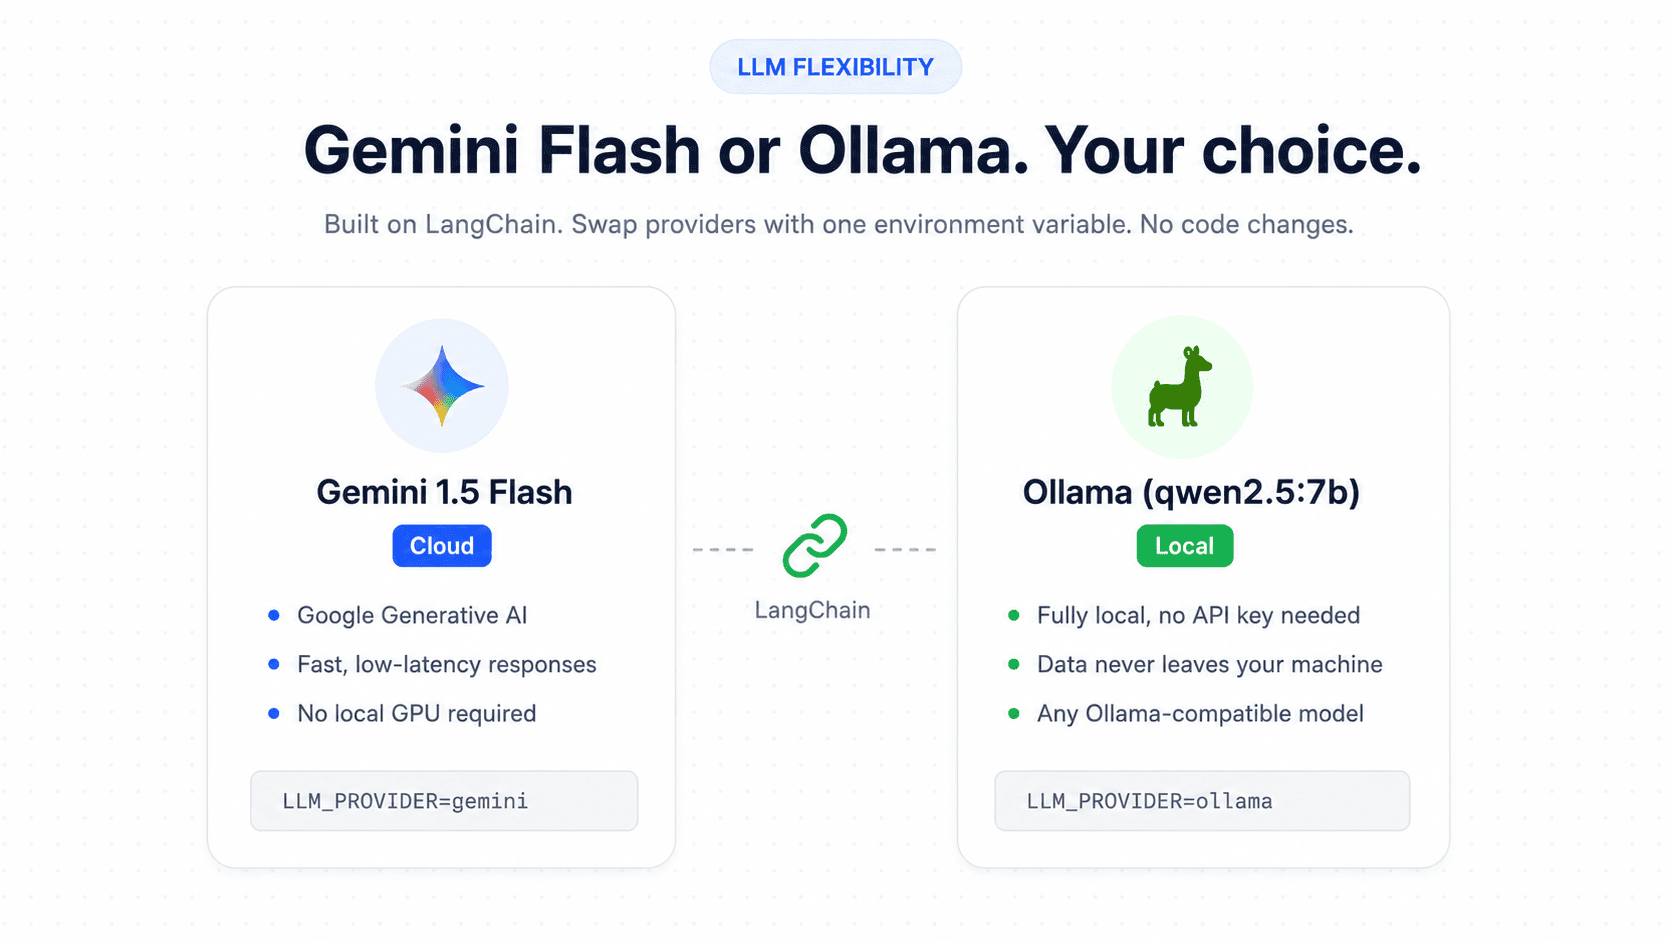
- Built on LangChain, the AI layer can switch between Gemini Flash and a fully local Ollama model with one environment variable.
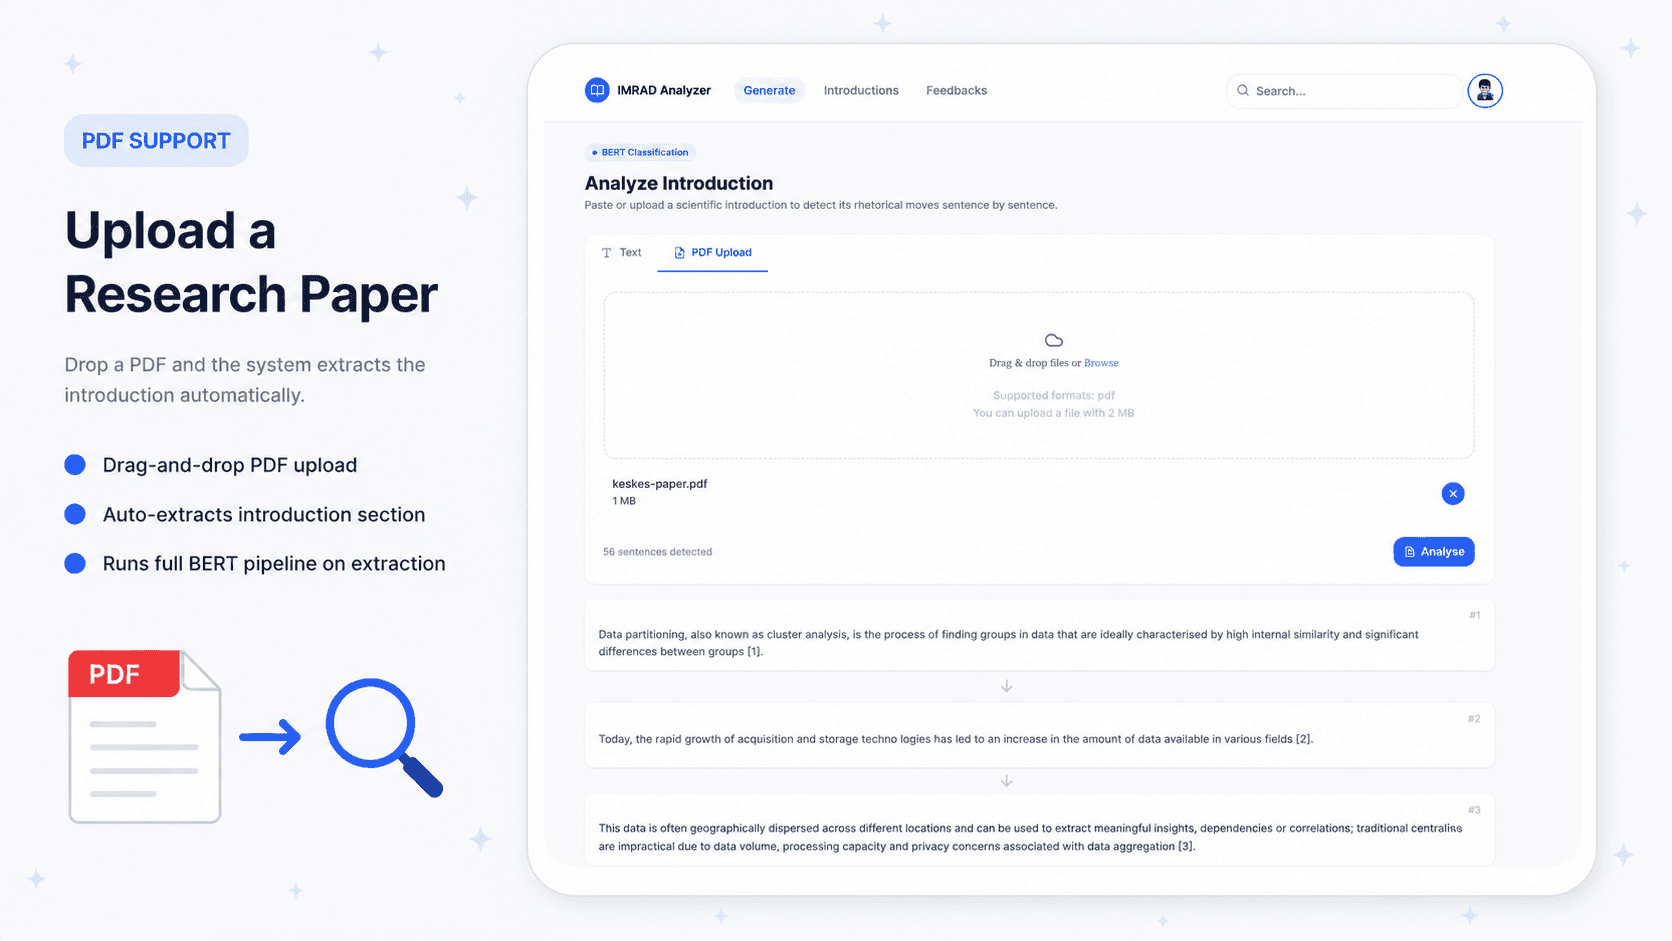
PDF Upload and Extraction
- Users drag and drop a research paper PDF and the system automatically extracts the introduction section.
- A dedicated FastAPI microservice handles extraction, then hands the text to the BERT classification pipeline.
- The full sentence-level classification runs on the extracted introduction with no manual copy-paste required.
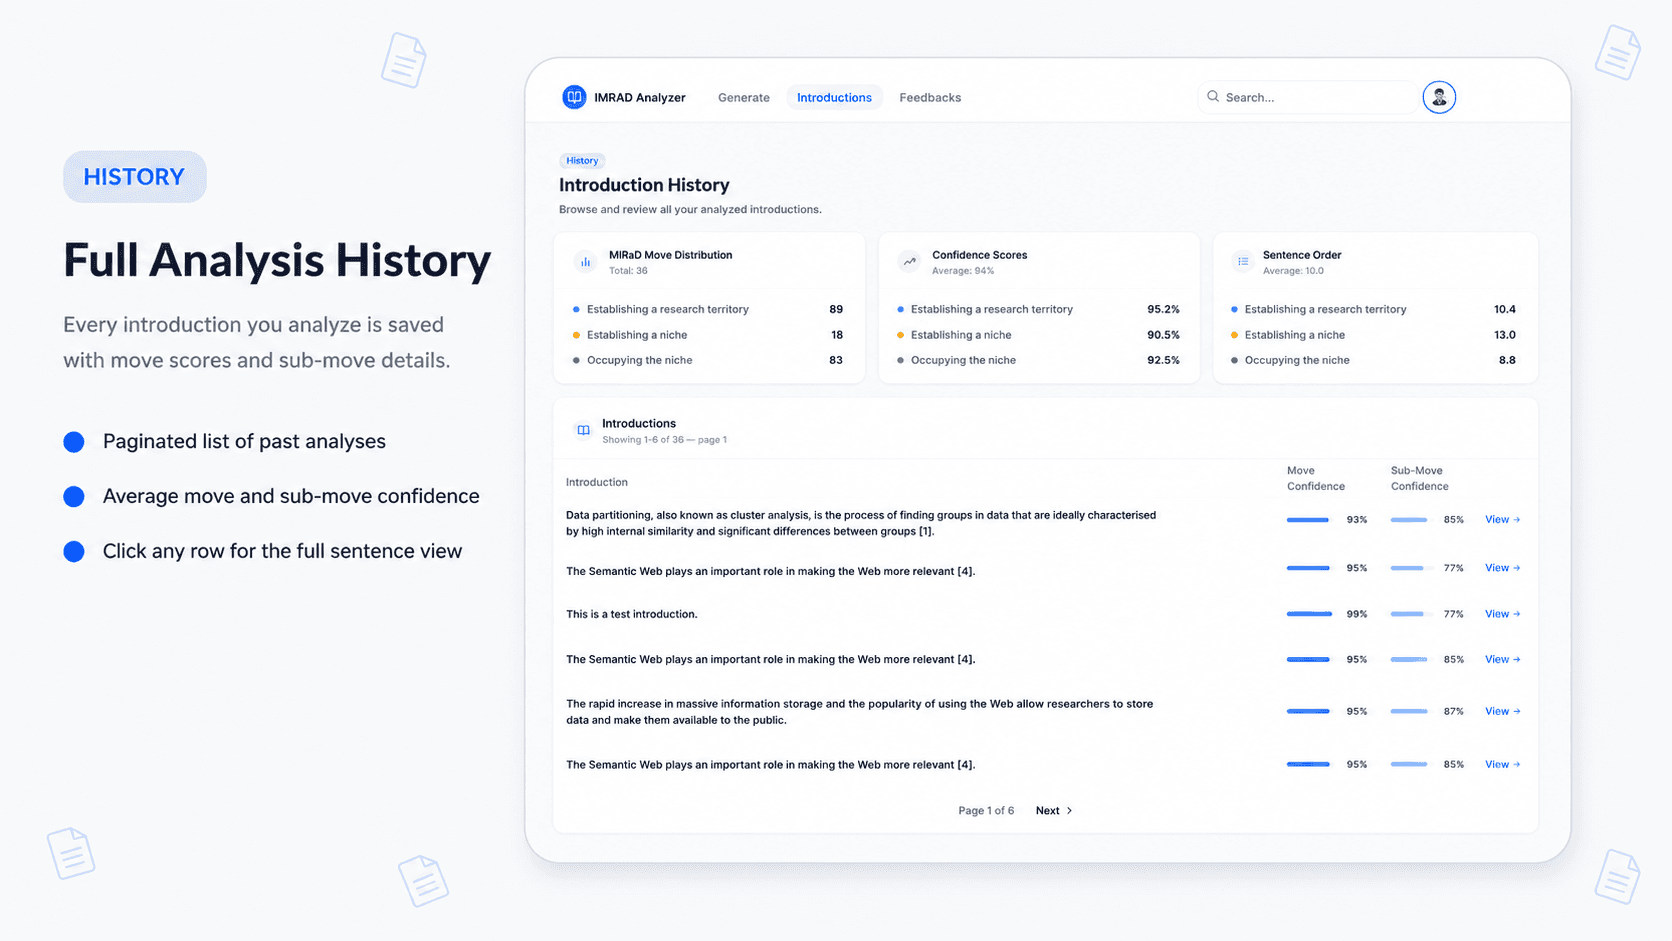
Full Analysis History
- Every analyzed introduction is saved with average move and sub-move confidence scores and a creation timestamp.
- Paginated list links directly to the full sentence-level breakdown for any past analysis.
- Lets users track how different papers score across Territory, Niche, and Occupy moves over time.
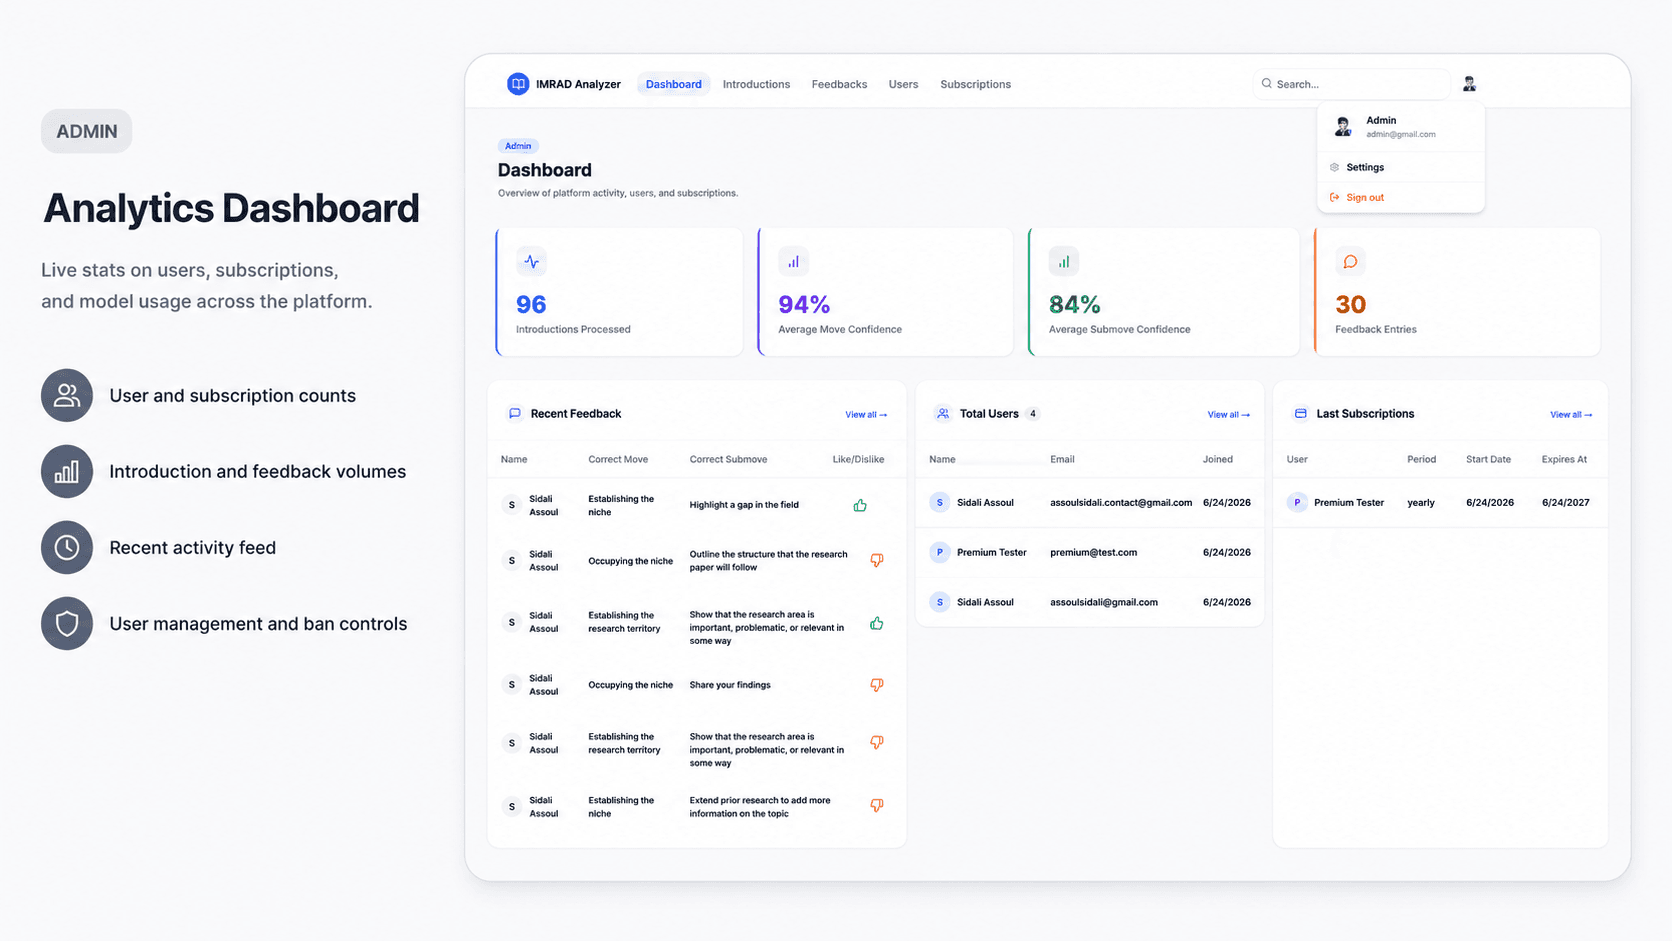
Analytics Dashboard
- Live stat cards show total users, premium subscribers, introductions analyzed, and feedbacks collected across the platform.
- Charts and a recent activity feed give admins a real-time view of platform usage without leaving the dashboard.
- User management and ban controls are accessible from the same page.
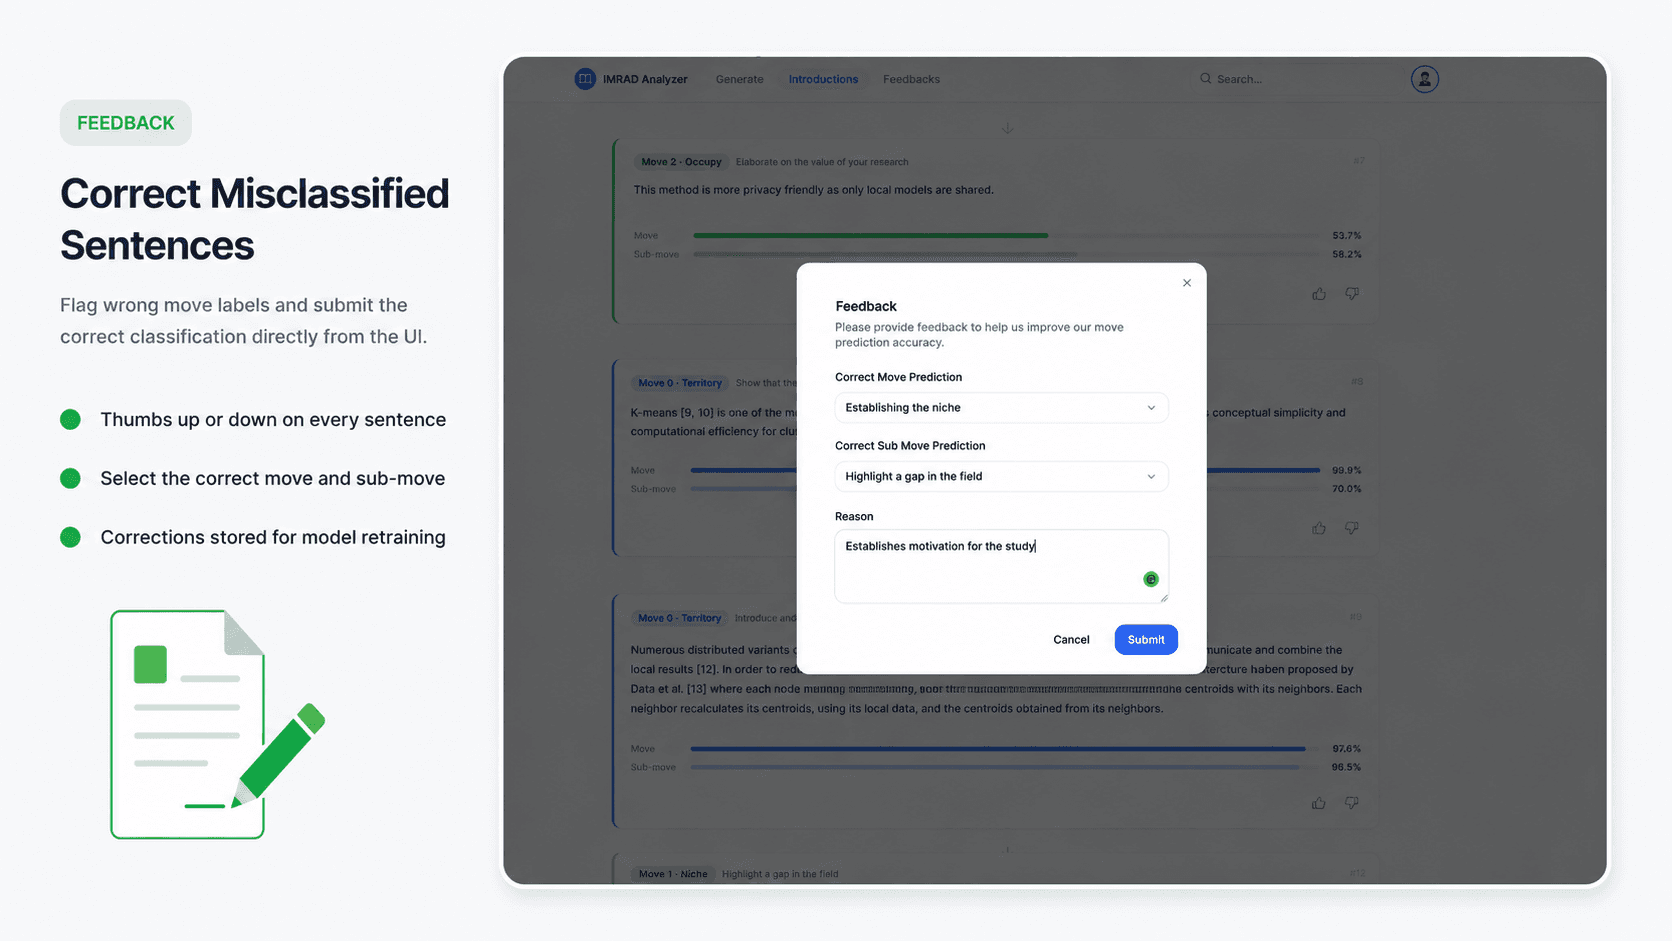
Correct Misclassified Sentences
- Users flag any sentence classification as wrong directly from the introduction detail page using thumbs-up/down controls.
- A correction dialog lets users select the correct move and sub-move before submitting.
- Every correction is stored and fed back into the BERT retraining pipeline to close the model quality loop.
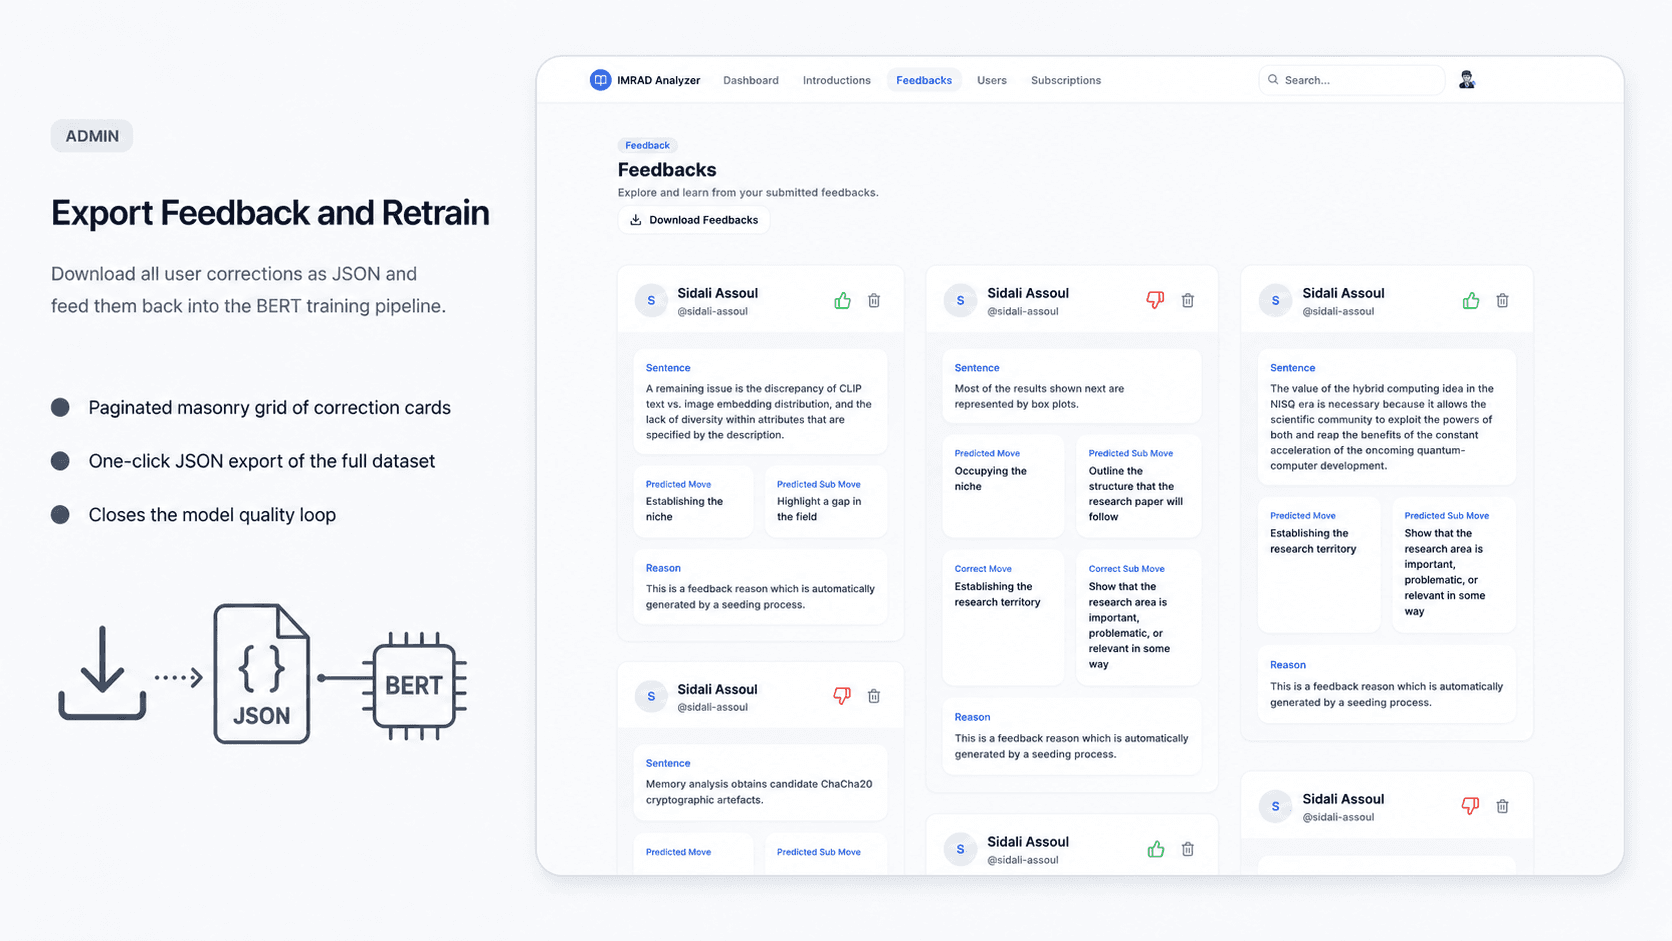
Export Feedback and Retrain
- Admins browse all user-submitted corrections in a paginated masonry grid of correction cards.
- One-click JSON export downloads the full correction dataset for use in the BERT training pipeline.
- Closes the model quality loop by routing real misclassification data back into fine-tuning.
Flexible LLM Backend via LangChain
- The AI analysis layer is built on LangChain and ships with two providers switchable via one environment variable.
- Set LLM_PROVIDER=gemini to use Gemini 1.5 Flash via the Google API, or LLM_PROVIDER=ollama for fully local inference.
- No code changes required to swap providers; any Ollama-compatible model works out of the box.
A project like this one?
Describe it in two lines on WhatsApp, and we reply directly.
Next projectContractsFlow